Revolut, Lloyds Bank Down: 1,500+ Reports Hit UK [2026]
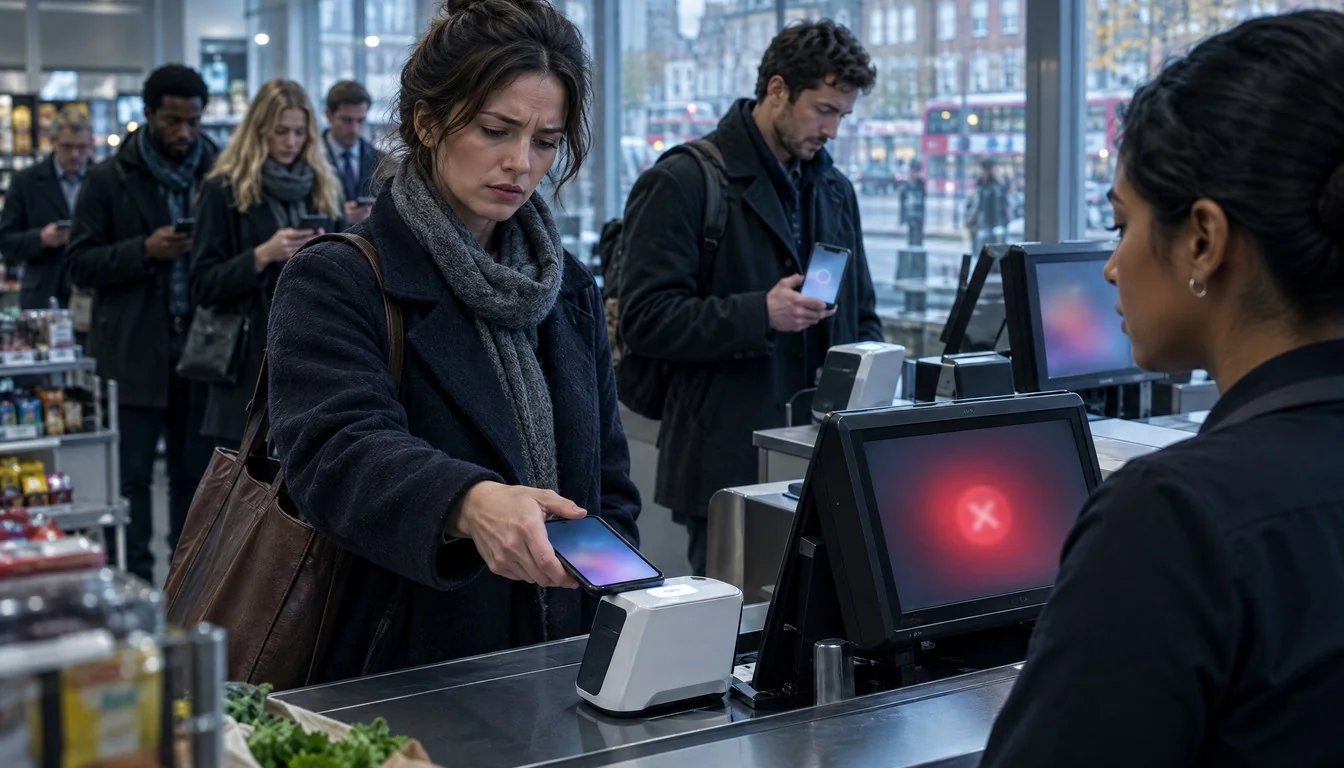
Revolut and Lloyds Bank customers across the United Kingdom spent Tuesday morning, October 20, 2026, locked out of basic banking tasks after a Google Cloud disruption rippled through services hosted in its London data center region. Card payments failed at the till, app logins timed out, and transfers stalled for thousands of users within minutes of the problem surfacing. Downdetector logged more than 1,500 UK reports about Revolut shortly after 08:00 BST, while Lloyds Bank customers separately flagged trouble reaching online banking and the mobile app around the same window.
The timing lines up with a Google Cloud status update confirming that “multiple services” were experiencing issues in Western Europe, with engineers investigating a problem rooted in the europe-west2 region, Google’s London data center zone. Revolut confirmed the disruption directly and said customer funds and data remained safe. Lloyds has not issued the same level of public detail, and the exact technical link between its app problems and the Google Cloud incident has not been confirmed. This is the clearest illustration yet of how a single regional cloud hiccup can knock out services that, on the surface, look unrelated to each other.
Don't miss new tech stories on Google
Add TrendinTech once in the Google app and our stories appear in your news suggestions.
Revolut Confirms Service Disruption Affecting Multiple Features
Revolut was the first of the two banks to publicly acknowledge the problem. The digital bank, which serves tens of millions of customers across Europe, said in a statement that it was “currently experiencing a service disruption affecting multiple services” and added that “all our customers’ money and data are safe.” The company said its engineering team had been working on a fix since the issue was first identified that morning and apologized to customers caught in the middle of it.
According to The Mirror, the services listed as partially unavailable on Revolut’s own status page included card payments, transfers, ATM withdrawals and customer support. For a bank that built its entire pitch around instant, app-first money management, those are not peripheral features. They are the product. Customers trying to pay for groceries or withdraw cash from an ATM were met with declined transactions instead of the usual real-time notification Revolut is known for.
Social media filled quickly with screenshots of failed payments and frozen balances, a familiar pattern whenever a digital-first bank goes dark, since Revolut customers have no branch to walk into and no landline number most people remember. The frustration showed up fastest where it is easiest to measure: outage-tracking sites.
Lloyds Bank Customers Hit With Login and App Failures
Lloyds Bank, one of Britain’s largest and oldest high street lenders, found itself in an unusual position alongside a digital challenger bank less than a third its age. Customers reported being unable to log into online banking or the Lloyds mobile app, with hundreds of reports logged on Downdetector through the morning. Unlike Revolut, Lloyds has not published the same granular breakdown of which systems were affected, and the company has not confirmed a direct technical dependency on Google Cloud for the specific services customers struggled to reach.
What makes the Lloyds angle notable is the contrast with where the bank’s public attention has been lately. Just a day earlier, on October 19, Lloyds Banking Group said it had held onto 15th place globally in the October 2026 Evident AI Index, remaining the highest-ranked UK bank in that ranking. A bank highlighting its artificial intelligence credentials one day and fighting basic login failures the next is an awkward juxtaposition that is unlikely to be lost on customers or regulators watching how UK lenders handle operational resilience.
Inside the Google Cloud Disruption in Europe West 2
Google Cloud’s own status page described the problem in technical, unglamorous terms: elevated errors and intermittent network failures affecting multiple services in the europe-west2 region, which covers London. The incident is reported to have started at roughly 06:08 UTC, well before most of the UK was awake, and Google’s engineers were still investigating as the morning wore on with no confirmed resolution time.
It is worth being precise about scope here, because “Google Cloud is down” and “a London region of Google Cloud has elevated errors” are different claims. Nothing in the reporting so far points to a total, worldwide Google Cloud failure. The disruption is regional, tied specifically to the London zone that underpins services for companies that chose to host European operations there for latency or data-residency reasons. For software engineers who have spent any time working with managed cloud infrastructure, that distinction matters: a single-region outage can still take down a company’s entire customer-facing product if that company never built redundancy into a second region.
Engineers following the incident also pointed to a specific grouping of affected services rather than a blanket outage. Based on reports gathered during the incident, the list touched on BigQuery Data Transfer Service, Cloud Filestore, Cloud Run, App Engine, Google Cloud NetApp Volumes, Google Kubernetes Engine and Managed Service for Apache Kafka, a spread that covers everything from data pipelines to the compute layer that modern banking apps lean on for backend processing.
What Google Cloud Said Publicly
Google Cloud’s status dashboard stated plainly that “multiple Google Cloud services are experiencing elevated errors and intermittent network failures in europe-west2 region.” The company later added, according to reporting reviewed by BBC News, that it apologized to all those affected by the disruption and that its engineering team continued to investigate the issue. Those two lines, an apology and a promise to keep looking, are the standard vocabulary of a cloud incident response, and they leave the harder question unanswered: how a regional network problem at one provider was able to reach into the daily banking habits of millions of people who have never heard of “europe-west2” and never will.
Is Google Cloud Actually to Blame for the Bank Outages?
This is the part of the story that deserves more caution than the headlines allow. The timing overlap between the Google Cloud incident and the Revolut and Lloyds outages is suggestive, not proven. Revolut’s own statement did not name Google Cloud as the cause of its disruption. Google’s status update, in turn, did not name Revolut or Lloyds specifically among the affected customers. What exists is a strong circumstantial case built on timing and the pattern of other companies reporting problems during the same window.
That nuance is easy to lose in a fast-moving news cycle, but it matters for anyone trying to understand genuine cloud concentration risk versus coincidence. A bank’s mobile app can fail for a dozen reasons that have nothing to do with its cloud provider: a bad internal deployment, a database migration gone wrong, a third-party payment processor hiccup. The responsible read of Tuesday’s events is that a regional Google Cloud problem and a cluster of UK banking app failures happened at the same time, in the same country, during the same two-hour window, and that the companies involved have not yet laid out the precise technical chain connecting the two.
It Wasn’t Just Banks: Who Else Reported Problems
Revolut and Lloyds were not alone. Reports during the same window named HSBC, Royal Mail, Rightmove, DPD and Screwfix among the services customers flagged as experiencing issues, according to outlets tracking Downdetector activity through Tuesday morning. That spread, from banking to parcel delivery to property listings to home improvement retail, is itself a useful piece of evidence for the cloud-concentration theory, since it is hard to imagine what those businesses have in common operationally other than relying on shared cloud infrastructure somewhere in their stack.
None of this is new territory for anyone who follows cloud infrastructure closely. TrendInTech’s coverage of a separate Yandex outage earlier this month showed how quickly a single infrastructure hiccup can generate a wave of outage reports that outpace the company’s own ability to explain what happened in real time. The pattern repeats because the underlying structure of the modern internet repeats: a small number of hyperscale cloud regions quietly sit underneath an enormous share of consumer-facing apps.
Reading the Downdetector Numbers
The shape of the complaints tells its own story about where the failure actually bit hardest. For Revolut, the breakdown recorded at 08:09 BST showed roughly 65% of reports concerning the app itself, 20% about access to funds and 8% about login problems. For Lloyds, the split skewed differently: nearly 40% of reports concerned online-banking login difficulties, and around 30% concerned the Lloyds app specifically.
| Bank | Top complaint category | Share of reports | Second complaint category | Share of reports |
|---|---|---|---|---|
| Revolut | App not working | ~65% | Access to funds | ~20% |
| Revolut | Login issues | ~8% | Other | ~7% |
| Lloyds Bank | Online banking login | ~40% | Mobile app | ~30% |
| Lloyds Bank | Other reported issues | ~30% | n/a | n/a |
The split suggests Revolut’s problem leaned more toward its mobile application layer failing to load or respond, while Lloyds customers were disproportionately stuck at the authentication step, the point where a banking app checks who you are before letting you see a balance. Different failure signatures do not rule out a shared root cause, but they are a reminder that “both banks went down” is not the same claim as “both banks failed in the same way.”
Timeline: How Tuesday Morning Unfolded
| Approximate time | Event |
|---|---|
| 06:08 UTC | Google Cloud reports elevated errors and intermittent network failures beginning in the europe-west2 London region |
| Early morning | Revolut customers begin reporting failed card payments and app errors |
| Early morning | Lloyds Bank customers report online-banking login failures and app problems |
| ~08:00 BST | Downdetector logs more than 1,500 UK reports for Revolut |
| 08:09 BST | Revolut report breakdown shows app, funds-access and login issues dominating complaints |
| Morning, ongoing | Google Cloud confirms investigation is underway; no confirmed resolution time given |
| Morning, ongoing | Revolut apologizes to affected customers and confirms money and data remain safe |
Why a Single Cloud Region Can Take Down So Many Unrelated Apps
There is a structural reason this keeps happening, and it has little to do with any one company’s engineering competence. Modern fintech and retail apps are built on managed cloud services precisely because reinventing databases, networking and compute infrastructure from scratch is slow and expensive. Renting that infrastructure from a hyperscaler, rather than building and running it in-house, is usually the economically rational choice. The tradeoff is that when the provider’s regional infrastructure has a bad morning, every customer sitting on that region feels it at roughly the same time, regardless of how well each individual company wrote its own application code.
Engineering teams at companies like Revolut do plan for this. Multi-region failover, where traffic automatically shifts to a healthy region when one goes dark, is a known pattern and something the industry has written extensively about, including in TrendInTech’s own walkthrough of building multi-cloud resilience with Terraform and Kubernetes. But failover of that kind is expensive to build, expensive to test, and genuinely hard to get right for a regulated financial product where data residency rules often require EU or UK customer data to stay within specific geographic boundaries. That regulatory constraint is itself part of why a London-specific Google Cloud region exists in the first place, and why so many UK-focused companies concentrate their infrastructure there.
Market and Industry Impact
For Revolut, the reputational stakes are higher than for a legacy bank like Lloyds, which still has nearly two centuries of brand trust to draw on even after a bad morning. Revolut’s entire value proposition rests on the promise that app-based banking is more reliable and more convenient than a branch visit, and an outage that blocks card payments and ATM withdrawals cuts directly against that pitch. The company has leaned heavily into new feature announcements this year, including the rollout of its AI assistant, AI by Revolut, across Europe and a UK-market stablecoin product, and a visible outage threatens to overshadow that momentum in the short term.
For the wider cloud infrastructure market, incidents like this one feed directly into a debate that TrendInTech has tracked closely around how AWS, Azure and Google Cloud compare on pricing and reliability. Every high-profile regional outage becomes ammunition for competitors pitching multi-cloud architectures, and for enterprise procurement teams who use “what happened last time this provider had a bad day” as a genuine input into vendor selection. Google Cloud remains the third-largest hyperscaler by most market measures, and a visible UK banking outage, even a partial and unconfirmed one, is the kind of story that shows up in competitor sales decks within the week.
Historical Context: This Keeps Happening to Someone
Cloud concentration risk is not a new concern, and regulators have been circling it for a while. UK and EU financial regulators have spent the past several years pushing banks to document their reliance on third-party cloud providers precisely because incidents like Tuesday’s keep demonstrating that a provider’s bad morning becomes the bank’s bad morning almost instantly. The specific technical failure mode changes each time: sometimes it is a networking fault, sometimes a bad software deployment, sometimes a hardware failure in a single data center. What stays constant is the exposure.
What makes this instance notable is the breadth of sectors hit in a single UK morning, spanning digital banking, a legacy high street bank, parcel delivery and property listings, all tracing back to reports clustering around the same cloud region at the same time. That breadth is exactly what resilience-minded regulators point to when they argue that “too many eggs in one cloud basket” is not an abstract worry but a Tuesday-morning reality for millions of ordinary customers trying to buy groceries or check a balance.
What Google Cloud and Revolut Said, In Their Own Words
Google Cloud’s status update put the technical scope of the problem plainly: “Multiple Google Cloud services are experiencing elevated errors and intermittent network failures in europe-west2 region,” the company said, in a statement reported by The Independent. As the incident continued, Google Cloud added that it continued to investigate, telling affected customers that “our engineering team continues to investigate the issue,” and separately said, “we apologize to all who are affected by the disruption.”
Revolut’s public messaging stuck to reassurance and transparency about the scope of the problem rather than assigning a cause. “We are currently experiencing a service disruption affecting multiple services. We can confirm that all our customers’ money and data are safe,” the company said. In a separate customer-facing statement reported by Express, Revolut said: “We are currently experiencing a service disruption affecting multiple features, which may result in some services being inaccessible. Our engineering team is actively working to restore full service as quickly as possible.” Lloyds Bank had not issued a comparably detailed public statement as of Tuesday morning.
How Google Cloud Stacks Up Against AWS and Azure on Resilience
No cloud provider is immune to regional incidents, and none of the big three hyperscalers can claim a perfect uptime record over any multi-year stretch. What differs between them is architecture philosophy, region count and how aggressively their enterprise customers are pushed toward multi-region deployment by default. The table below summarizes the broad competitive positioning relevant to this incident, based on each provider’s own published service structure rather than incident-specific claims.
| Provider | UK-relevant region | Typical enterprise resilience pattern |
|---|---|---|
| Google Cloud | europe-west2 (London) | Zonal and regional redundancy available; multi-region failover requires customer configuration |
| AWS | eu-west-2 (London) | Multiple availability zones per region; cross-region failover is opt-in architecture |
| Microsoft Azure | UK South / UK West | Paired-region model designed for UK data residency and disaster recovery |
The common thread across all three providers is that resilience beyond a single zone is largely something the customer has to build and pay for, not something that comes free by default. That is the uncomfortable truth sitting underneath Tuesday’s outage: Revolut, Lloyds and every other company that got caught up in the reports made an infrastructure decision at some point, whether explicit or by default, about how much regional redundancy to buy. For readers curious about the mechanics of running containerized workloads across providers without lock-in, TrendInTech’s walkthrough on deploying containers with AWS Fargate and the comparison of container orchestration costs across ECS and EKS both get at the underlying tradeoffs engineering teams weigh when they decide how much redundancy is worth the price tag.
Five Predictions for What Happens Next
- Expect Revolut and Lloyds to publish formal post-incident statements once services are fully restored, likely including a root-cause summary, since both companies operate under UK financial-conduct scrutiny that expects transparency after customer-facing outages.
- UK regulators, who have already pushed banks to document third-party cloud dependency, are likely to cite this incident as fresh evidence in ongoing discussions about operational resilience rules for critical third-party providers.
- Rival cloud providers will use this outage, however partial and unconfirmed the causal chain remains, in competitive pitches to UK financial-sector prospects currently evaluating cloud vendors.
- Expect renewed internal pressure inside affected companies to invest in multi-region failover architecture, even though that investment is expensive and was previously deprioritized in favor of feature development.
- Coverage of this specific incident will fade within days once services are restored, following the familiar pattern of outage stories, but it will be referenced again the next time a similar incident hits a different company on a different cloud region.
What Affected Customers Should Do Right Now
For Revolut and Lloyds customers currently locked out, the practical advice is unglamorous but important. Revolut has confirmed that customer funds and data are safe, so the underlying balance is not at risk even though the app may show errors or stale information. Customers with urgent payments due should have a backup payment method ready, since card declines during the outage window are an infrastructure symptom, not a reflection of account balance. Anyone needing to withdraw cash should check whether ATM withdrawals have been restored before relying on them, since that service was specifically flagged as affected.
For engineers and IT teams reading this with a professional interest rather than a personal banking concern, Tuesday’s incident is a useful real-world case study in why status pages matter and why monitoring your own dependency chain, not just your own servers, is part of the job now. A simple health check against a provider’s public status endpoint can give an application early warning before customer complaints start arriving.
curl -s https://status.cloud.google.com/incidents.json | grep -i "europe-west2"That kind of lightweight check will not prevent an outage, but it buys a company minutes of lead time to switch customer messaging from silence to transparency, which is exactly the gap Revolut tried to close with its own public statement on Tuesday.
The Bigger Picture for Cloud-Dependent Banking
Strip away the specific company names and Tuesday’s story is a familiar one: a regional cloud hiccup, a cluster of outage reports across unrelated sectors, a reassuring corporate statement about safety, and an unresolved question about exact causation that may never be fully answered in public. What makes this version notable is the sector involved. Banking has spent the past decade moving steadily onto cloud infrastructure in the name of speed and cost savings, and incidents like this one are the visible cost of that bet whenever the underlying infrastructure has a bad morning. Readers who want the fuller picture of how Google’s cloud infrastructure investments and regional footprint have been expanding can find useful context in TrendInTech’s report on Google’s confirmed data center expansion, a reminder that the same company racing to build more capacity is also the one whose London region stumbled on Tuesday.
None of this means cloud infrastructure is a bad bet for financial services. It means the resilience conversation is incomplete if it stops at “which provider is cheapest” and does not seriously account for “what happens to our customers when our provider’s region has a bad morning.” Tuesday gave UK banking customers, and the engineers who build the apps they rely on, a fresh and very concrete answer to that question.
Frequently Asked Questions
Is Revolut down right now?
Revolut confirmed a service disruption affecting multiple features on the morning of October 20, 2026, including card payments, transfers, ATM withdrawals and customer support. The company said it was actively working to restore full service and confirmed customer money and data remained safe.
Is Lloyds Bank down too?
Lloyds Bank customers reported problems with online banking and the Lloyds mobile app on the same morning, with hundreds of reports logged on Downdetector. Lloyds has not published the same level of detail as Revolut about which systems were specifically affected.
Did Google Cloud cause the Revolut and Lloyds outages?
A Google Cloud disruption in its europe-west2 London region was happening at the same time as the bank outages, and reporting described the connection as likely but not officially confirmed. Revolut’s own statement did not name Google Cloud as the cause, and Google’s status update did not name Revolut or Lloyds specifically.
Is my money safe if Revolut is down?
Revolut explicitly confirmed that all customer money and data remained safe during the disruption. An app or payment outage is a service availability problem, not a sign that account balances or stored funds are at risk.
What other companies were affected by the Google Cloud outage?
Reports during the same window named HSBC, Royal Mail, Rightmove, DPD and Screwfix among services customers flagged as experiencing problems, in addition to Revolut and Lloyds Bank.
When will the Google Cloud outage be fixed?
Google Cloud had not confirmed an exact resolution time as of Tuesday morning. The company said its engineering team continued to investigate the elevated errors and intermittent network failures in the europe-west2 region.
What is europe-west2 and why does it matter?
Europe-west2 is Google Cloud’s data center region covering London. Many UK-focused companies host infrastructure there for lower latency and to meet UK data-residency requirements, which means a problem in that single region can affect a wide range of unrelated UK businesses at once.
Could this kind of outage happen again?
Yes. Regional cloud outages are a recurring pattern across every major provider, and companies that have not built multi-region failover into their architecture remain exposed whenever their primary cloud region has a disruption, regardless of which provider they use.
Related Coverage
Yusuf Demir
Yusuf Demir is the Cloud & Software Reporter at TrendinTech, where he covers cloud infrastructure, enterprise platforms, developer tools and the digital transformation of businesses in the UK and the United States. He is most interested in the gap between vendor roadmaps and the systems engineers actually run, and in what the cloud bill looks like once the free credits expire.
All stories by Yusuf Demir (392)