Google TorchTPU Open Source: 450 PyTorch Ops on TPUs [2026]
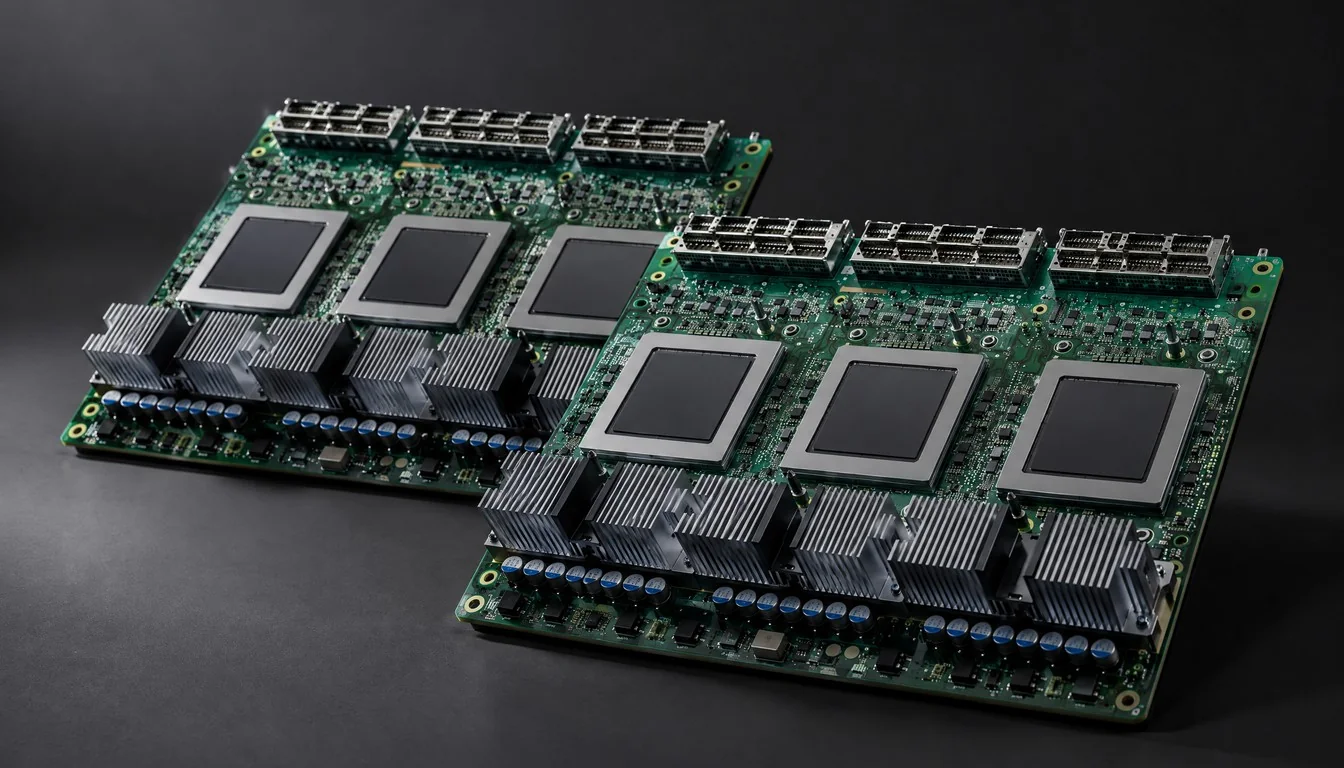
Google open-sourced TorchTPU on October 20, 2026, at the PyTorch Conference in San Jose, handing developers a native PyTorch backend for its Tensor Processing Units that Google built together with Meta’s PyTorch engineering team. The release landed one day after Amazon pushed out its own PyTorch port for Trainium chips, and together the two moves mark the most direct software challenge yet to Nvidia’s grip on how AI code gets written and run.
TorchTPU is not a new chip. It is a software layer that lets existing PyTorch code target Google’s TPUs the same way it already targets Nvidia GPUs, in many cases with little more than a configuration change rather than a rewrite. That distinction matters because the real barrier to leaving Nvidia hardware has rarely been the silicon itself. It has been the code written against CUDA, Nvidia’s proprietary programming platform, which has anchored a decade of machine learning tooling, libraries, and institutional muscle memory.
Don't miss new tech stories on Google
Add TrendinTech once in the Google app and our stories appear in your news suggestions.
What Google Announced at the PyTorch Conference
Bill Jia detailed the release on the Google Cloud blog, describing TorchTPU as a project built to let PyTorch, TorchServe, and the surrounding ecosystem run on Google TPUs without forcing developers into a separate tensor abstraction. The companion post on the PyTorch blog called it an open-source collaboration between Google and Meta that introduces a native, principled PyTorch backend for Google TPUs, promising out-of-the-box model execution and migration while targeting competitive inference and training throughput.
Alongside TorchTPU, Google and its partners published three companion repositories: vLLM-TorchTPU and SGLang-TorchTPU, which bring TPU-native serving to two of the most widely used open-source inference engines, and a TPU-oriented build of TorchTitan, Meta’s large-scale training framework. The project is released under the Apache 2.0 license and is hosted publicly on GitHub under the google-pytorch organization, with wheels built for Linux x86-64 across Python 3.11 through 3.14.
TechCrunch framed the announcement bluntly, reporting that Google has joined Amazon in attacking Nvidia’s stronghold with AI app developers by making it far easier to keep existing PyTorch code and simply point it at a different accelerator. TechCrunch’s coverage noted that most AI applications are still written by default for Nvidia GPUs, and that Google’s tool is aimed squarely at loosening that default.
How TorchTPU Actually Works
The technical pitch is simplicity. A developer who already has PyTorch code pointed at a GPU changes the device string and, in Google’s description, the rest of the workflow carries over. The project documentation shows the pattern directly:
x = torch.tensor([1.0, 2.0, 3.0], device="tpu")
y = torch.tensor([4.0, 5.0, 6.0], device="tpu")
Underneath that simple device string sits a fairly involved compiler path. TorchTPU lowers PyTorch’s ATen operator set to StableHLO, the portable representation that Google’s XLA compiler consumes to generate TPU machine code. Google says the initial release supports roughly 450 ATen operators, including forward and backward passes for the operators used by the architectures most teams actually train and serve today, and it introduces an eager-mode optimization Google calls DeferAndFuse alongside standard support for torch.compile.
Eager mode and torch.compile
PyTorch’s appeal over the years has rested heavily on eager execution, the ability to run code line by line and debug it like ordinary Python rather than compiling a static graph upfront. Historically, that convenience came at a cost on TPUs, where Google’s older PyTorch/XLA path leaned on graph compilation and often behaved differently enough from GPU-native PyTorch to frustrate teams trying to port code over. TorchTPU’s DeferAndFuse mode is Google’s attempt to keep the eager-mode debugging experience intact while still batching and fusing operations for TPU efficiency behind the scenes.
Correctness and operator coverage
Google’s own published benchmarks, cited on the PyTorch blog, reported 638 of 657 tested operators matching GPU results, a 97 percent correctness rate, and separately verified correct numerics on 834 of 839 causal language models drawn from a five-thousand-model test corpus for cases involving bounded dynamic shapes. Those numbers suggest a backend that is broad but still has edge cases, which tracks with Google’s own framing of TorchTPU as in active development rather than a finished, universal replacement for every existing TPU workload.
The Nvidia Lock-In Problem, Explained
Nvidia’s advantage was never just about having the fastest chip in a given quarter. CUDA, the parallel computing platform Nvidia built up over roughly 17 years, became the substrate that nearly every major deep learning framework, library, and research paper assumed as a baseline. Writing a model, publishing a kernel, or shipping an inference server almost always meant writing it for CUDA first and everything else second, if at all. That dynamic let Nvidia charge a premium for its GPUs because switching away meant rewriting and revalidating large amounts of infrastructure code, not just swapping hardware.
TorchTPU attacks that dynamic from the software side rather than the silicon side. Instead of asking Nvidia’s competitors to match CUDA’s raw performance, Google is trying to make the switching cost itself smaller by preserving the PyTorch programming model that most engineers already know. Google’s documentation describes TPUs joining GPUs and CPUs as a native PyTorch execution target, which is a deliberate framing: TPUs are presented as one more device string, not a separate universe requiring a different mental model.
It is worth being precise about what is and is not confirmed here. Neither Google’s official blog post nor the PyTorch announcement uses the phrase “breaking Nvidia’s GPU lock-in.” That characterization comes from outside commentary, including the Tech Buzz’s framing of the release as a tool designed to make it dead simple for developers to migrate applications off Nvidia GPUs and onto alternative hardware. The more defensible, narrower claim is that TorchTPU lowers a specific software migration barrier. CUDA remains the dominant GPU software platform, and TorchTPU does not replace it so much as give TPUs a native on-ramp into a PyTorch world that previously treated Nvidia hardware as the default.
Cost and Throughput Numbers Google Is Pointing To
Google’s PyTorch blog post included specific benchmark figures tied to two workload categories it calls InferenceX and AgentX. The company said TorchTPU achieved the lowest cost per million tokens overall on InferenceX at an 8K-token-in, 1K-token-out configuration, pricing out at 2.01 cents per million tokens, down from 3.6 cents in what Google described as its September debut of the same benchmark. On AgentX, a workload meant to represent agentic, conversational-style traffic, Google reported the lowest cost per million tokens at 0.83 cents, along with what it called state-of-the-art interactivity and full pareto frontier leadership on the cost-versus-responsiveness curve.
| Benchmark | Workload shape | Reported cost per million tokens | Prior figure cited |
|---|---|---|---|
| InferenceX 8K/1K | 8,000 tokens in, 1,000 tokens out | 2.01 cents | 3.6 cents (September debut) |
| AgentX | Agentic, interactive traffic pattern | 0.83 cents | Not separately broken out |
| TorchTitan on Ironwood | Large-scale training | Validated at up to 8,000 TPUs | Not applicable |
Those figures come from Google’s own blog post rather than an independent third-party benchmark, so they should be read as a vendor’s best-case numbers rather than an audited comparison against Nvidia instances running equivalent workloads. Still, the direction is consistent with a broader pattern this year: Google, AWS, and others are increasingly willing to publish head-to-head cost claims in a market where GPU scarcity has kept Nvidia pricing elevated, a dynamic also visible in how AWS, Azure, and Google Cloud have diverged on GPU pricing this year as each cloud leans on its own custom silicon to blunt Nvidia’s margins.
Which TPU Generations TorchTPU Supports
Google’s documentation lists a wide span of TPU hardware as compatible with the TorchTPU serving and training path, spanning older Cloud TPU generations through its newest systems. TPU v6e, branded Trillium, and TPU7x, branded Ironwood, are the generations Google highlights for the primary TorchTPU serving workflow, while TPU v4, v5p, and v5e remain supported Cloud TPU generations referenced in the same documentation.
| TPU generation | Brand name | Role in TorchTPU documentation |
|---|---|---|
| TPU v3 / v4 | (unbranded) | Listed as supported Cloud TPU generations |
| TPU v5e / v5p | (unbranded) | Listed as supported Cloud TPU generations |
| TPU v6e | Trillium | Supported for the TorchTPU serving workflow, native multi-NIC architecture |
| TPU7x | Ironwood | Supported for TorchTPU serving; TorchTitan validated at up to 8,000 Ironwood TPUs |
| TPU 8i / TPU 8t | Eighth-generation TPU family | Google’s newest announced TPU system, claimed 80% better price-performance than the prior generation |
That eighth-generation pairing, TPU 8i for inference and TPU 8t for training, was first announced in April 2026, and Google has continued to position it as sitting alongside Nvidia GPU instances in its cloud catalog rather than displacing them outright. The memory story behind TPU 8i is part of Google’s pitch too: Google says the chip pairs 288 gigabytes of high-bandwidth memory with 384 megabytes of on-chip SRAM, three times more on-chip memory than the prior generation, aimed at keeping a model’s active working set on the chip instead of shuttling it back and forth. That kind of memory-bandwidth arms race is also playing out on the Nvidia side of the ledger, where suppliers like Micron have mapped out HBM4 roadmaps specifically to keep pace with AI workloads that need ever more bandwidth per chip.
Meta’s Role in the Collaboration
TorchTPU is officially credited as a joint effort between Google and the PyTorch team at Meta, which is notable given that Meta remains one of the largest buyers of Nvidia GPUs in the world. Meta’s involvement looks less like a strategic pivot away from Nvidia and more like stewardship of PyTorch itself, since Meta originally built and still maintains large parts of the framework through the PyTorch Foundation. Nothing in Meta’s own announcements confirms that the company is shifting its internal training or inference infrastructure toward TPUs, or that its newly launched Muse Wonder and Muse Wonder Full model family, which Meta has called its most capable models to date, runs on anything other than Nvidia hardware. Meta’s recent frontier-model work, including the pricing moves around Muse Wonder as a frontier model, continues to sit in a separate conversation from the TPU portability story, even as Meta’s engineers are the ones who helped build the bridge.
What Meta gains is more straightforward: if PyTorch runs natively and well on TPUs, that strengthens PyTorch’s position as the default framework for the entire industry, regardless of which company’s chips end up underneath. A framework that only works well on one vendor’s hardware is a weaker foundation than one that genuinely works across GPUs, TPUs, and custom accelerators from AWS or anyone else.
The Serving Ecosystem: vLLM, SGLang, llm-d, and TorchTitan
A PyTorch backend is only as useful as the tools built around it, and Google used the conference to fill in that layer. vLLM-TorchTPU compiles PyTorch model forward passes for Cloud TPUs through the TorchTPU and XLA compiler path, giving one of the most widely deployed open-source inference servers a TPU-native option rather than a bolt-on. SGLang-TorchTPU, developed jointly by RadixArk, Google, and Meta according to the LMSYS announcement, extended support to models including GPT-OSS, Qwen3-Coder-480B, Qwen3.5, DeepSeek-V3.1 and R1, Kimi-K2.6, MiMo-V2.5-Pro, and Qwen3-VL, with the team saying it is working toward adding DeepSeek V4.1 Flash and Reflection Beam with a stated goal of day-zero TPU support for new open models by the first quarter of 2027.
Google also announced llm-d 1.0, an open, Kubernetes-native distributed inference stack that spans both TPUs and GPUs, with native PyTorch serving through TorchTPU built into the upstream versions of vLLM and SGLang. Google additionally published documentation for multi-host TPU serving using Ray, and introduced an OpenTelemetry-based TPU AI Telemetry Collector Agent capable of routing TPU hardware telemetry to Google Cloud Monitoring, Google Managed Prometheus, or self-hosted Grafana instances, giving operations teams visibility into TPU fleets that previously required more specialized tooling.
Amazon Made the Same Move a Day Earlier
Google’s timing was not accidental in the sense that it followed a nearly identical announcement from Amazon. On October 19 and 20, 2026, PyTorch’s own blog confirmed that Amazon Web Services introduced TorchNeuron, a native PyTorch backend for AWS Trainium chips, also released under the Apache 2.0 license and opened as a public beta on October 20, installable with a simple pip install torch-neuronx command from AWS’s Neuron repository. That two cloud providers shipped nearly identical PyTorch-native accelerator backends within 24 hours of each other is itself a signal: both Google and Amazon have independently concluded that the fastest way to pry developers off Nvidia-first defaults is to meet them exactly where they already are, inside ordinary PyTorch code, rather than asking them to learn a new framework or a new abstraction layer.
It also means Nvidia is now facing parallel software pressure from two of the three largest cloud providers at once, even as Nvidia’s own hardware continues to sell as fast as the company can produce it. Nvidia’s RTX Spark line, which began shipping globally on October 16, 2026, through partners including ASUS, Dell, HP, Lenovo, Microsoft, and MSI at a starting price of $2,599, shows that Nvidia is not standing still either, continuing to push CUDA, DLSS, and TensorRT deeper into both data centers and local workstation hardware even as TPU and Trainium alternatives mature. The RTX Spark launch and its pricing details arrived just days before Google’s TorchTPU release.
What Happens to PyTorch/XLA
TorchTPU’s arrival raises an obvious question about PyTorch/XLA, the older project that has handled PyTorch-on-TPU workloads up to now. A developer post circulating after the announcement claimed PyTorch/XLA has been deprecated and is scheduled for repository archiving on November 15, 2026. That claim has not been confirmed in Google’s own blog post or in the official PyTorch announcement, and it should be treated as an unconfirmed secondary report rather than settled fact. What is confirmed is that Google is actively steering new workloads toward TorchTPU: the company’s own materials recommend TorchTPU for new projects, and a separate interoperability path called torchax, which runs PyTorch models on Cloud TPUs by routing through JAX, remains available as a distinct option for teams that need it.
Market Reaction and Why Nvidia Isn’t Panicking Yet
Nvidia’s public response to the TorchTPU launch has been effectively silent, and that silence is itself informative. Nvidia’s own newsroom in the days around the announcement focused on CUDA Toolkit 13.4, which added Windows on Arm support and preview compatibility with Nvidia’s upcoming Rubin architecture, and on the continued rollout of RTX Spark hardware. Nvidia continues to describe CUDA as enabling native support across more than 150 million Nvidia RTX AI PCs and GPUs in the cloud, a scale argument that a single open-source backend release does not immediately undercut.
The more interesting pressure point sits further down the supply chain. If TPUs and Trainium become genuinely interchangeable with GPUs at the PyTorch code level, the competitive battle shifts away from basic compatibility and toward which chip is cheapest and fastest for a given workload, a question that favors whichever cloud has the newest custom silicon and the most aggressive pricing. That shift would also ripple into chip supply more broadly, in a market where Nvidia’s position has already been eroding in specific regions. In China, for instance, Nvidia’s AI chip market share has reportedly fallen to around 34 percent as Huawei’s share climbed to roughly 28 percent, showing that non-Nvidia AI silicon can gain ground quickly once a viable software path exists, even without a PyTorch backend as clean as TorchTPU.
Historical Context: A Decade of CUDA’s Moat
CUDA’s dominance did not happen overnight, and it is worth remembering how it was built. Nvidia began investing in general-purpose GPU computing long before deep learning became mainstream, and when the 2012 AlexNet breakthrough showed GPUs could train neural networks dramatically faster than CPUs, CUDA was already the only mature toolchain positioned to capture that demand. Every major framework that followed, from Theano and Caffe through TensorFlow and eventually PyTorch, was built with CUDA as the primary backend, which meant an entire generation of researchers, engineers, and open-source libraries grew up assuming Nvidia hardware as the default target.
Google’s TPUs have existed since 2016, originally as an internal project to accelerate Google’s own search and translation workloads, and Google has spent years trying to convince outside developers to use them. Earlier attempts, including PyTorch/XLA, worked but came with enough friction, different debugging behavior, and compatibility gaps that many teams simply defaulted back to GPUs for anything outside Google’s own infrastructure. TorchTPU represents Google’s clearest attempt yet to remove that friction rather than ask developers to tolerate it, and the fact that Meta’s own PyTorch team co-built it lends the project a legitimacy that a Google-only effort would have lacked.
What This Means for Developers Right Now
For teams already running PyTorch workloads, the practical takeaway is that evaluating TPUs no longer requires a separate engineering track. A team that wants to test whether Google’s Ironwood TPUs are cheaper or faster for a specific training or serving job can, in principle, point existing code at a TPU device string, run the vLLM-TorchTPU or SGLang-TorchTPU serving path, and compare results directly against their current GPU setup. That lowers the cost of experimentation significantly compared to a year ago, when testing TPUs meant learning a distinct programming model.
It is not, however, a guarantee of painless migration for every workload. With roughly 450 of PyTorch’s ATen operators supported and a 97 percent correctness rate against GPU results in Google’s own testing, some models, especially those relying on less common or custom operators, will still hit gaps. Google has been explicit that the project is in active development and has invited feedback on which models and workloads to prioritize next, language that signals a genuine early-stage release rather than a finished product dressed up as one.
Five Predictions for the Next Year
- Expect Microsoft to respond with its own native PyTorch backend for Azure’s Maia accelerators, following the same pattern Google and Amazon have now both set, since none of the big three clouds can afford to be the one still asking developers to learn a separate framework.
- TorchTPU’s operator coverage will likely climb from roughly 450 toward broader parity with CUDA over the next two to three releases, following the same kind of rapid-iteration pattern PyTorch/XLA went through earlier in its life, just compressed into a shorter window given the competitive pressure.
- Nvidia will keep leaning on scale and ecosystem depth rather than software lock-in as its primary defense, continuing to push CUDA-X libraries like the newly adopted cuPotential library for agent building, and continuing to ship consumer-facing hardware like RTX Spark to keep developers inside its tooling even where portability exists elsewhere.
- Benchmarks comparing TPU and GPU cost-per-token will become a standard feature of cloud AI marketing over the next two to three quarters, following the InferenceX and AgentX pattern Google introduced, as cloud providers compete to prove their custom silicon undercuts Nvidia instance pricing.
- PyTorch/XLA’s status will likely be clarified officially within the next month or two, either with a formal deprecation notice from Google matching the unconfirmed November 15 archive date, or with an official statement walking that back, given how much attention the ambiguity has already drawn from developers watching the transition.
Competitive Backends Compared
Stacking the major native PyTorch accelerator backends side by side shows just how fast this shifted from a Google-only project into an industry pattern within a single week.
| Backend | Vendor | Hardware target | License | Release status (Oct. 20, 2026) |
|---|---|---|---|---|
| TorchTPU | Google, with Meta | Google Cloud TPUs (v4 through TPU7x/Ironwood) | Apache 2.0 | Open source, public release |
| TorchNeuron | Amazon Web Services | AWS Trainium | Apache 2.0 | Open source, public beta |
| PyTorch/XLA | Google Cloud TPUs | Open source | Status disputed; unconfirmed archival claim for Nov. 15, 2026 | |
| CUDA-native PyTorch | Nvidia (via PyTorch core) | Nvidia GPUs | Open source | Default, long-standing |
The Bigger Picture for Cloud AI Spending
None of this happens in a vacuum. Every major cloud provider is spending enormous sums on AI infrastructure, and the chip underneath each dollar of that spending increasingly comes down to a build-versus-buy decision. Google has been building TPUs for its own account for a decade; Amazon has been doing the same with Trainium and Inferentia since 2019. What changed this week is that both companies finally shipped the software glue that makes those custom chips usable by outside developers without a steep learning curve, rather than keeping the best tooling for internal use only. That is a meaningfully different competitive posture than simply selling TPU or Trainium instances at a discount, since it attacks the actual reason many teams stayed on GPUs in the first place.
Whether that translates into meaningfully lower Nvidia GPU demand depends on factors well beyond this one release, including how quickly TorchTPU’s operator coverage matures, how aggressively Google and Amazon price their custom silicon against Nvidia instances, and whether enterprise customers are willing to run production workloads on a backend Google itself describes as still under active development. For now, TorchTPU is best understood as a serious, credible crack in the CUDA moat rather than a finished replacement for it.
Frequently Asked Questions
What is TorchTPU?
TorchTPU is an open-source, native PyTorch backend for Google’s Tensor Processing Units, built by Google together with Meta’s PyTorch team and released on October 20, 2026, at the PyTorch Conference in San Jose.
Does TorchTPU replace PyTorch/XLA?
Google positions TorchTPU as the recommended path for new PyTorch workloads on TPUs. A secondary, unofficial report claims PyTorch/XLA will be archived on November 15, 2026, but that has not been confirmed in Google’s or PyTorch’s own announcements.
Does TorchTPU work with models other than Google’s own?
Yes. Google and its partners listed support for third-party open models including GPT-OSS, Qwen3-Coder-480B, Qwen3.5, DeepSeek-V3.1 and R1, Kimi-K2.6, MiMo-V2.5-Pro, and Qwen3-VL through the SGLang-TorchTPU serving path.
Is TorchTPU available on hardware other than Google TPUs?
No. The official Google and PyTorch announcements describe TorchTPU specifically as a backend for Google TPUs. Claims that it supports other non-Nvidia chips are not confirmed in the official materials.
Does this mean Nvidia’s CUDA platform is being replaced?
No. CUDA remains the dominant GPU software platform. TorchTPU reduces a specific software migration barrier for teams that want to try TPUs, but it does not eliminate Nvidia’s broader lock-in advantage across the industry.
How much code do I need to change to use TorchTPU?
Google describes the migration as requiring minimal code changes in most cases, often as simple as pointing a PyTorch tensor or model at a TPU device string instead of a GPU device string, though teams using less common operators may hit compatibility gaps given the roughly 450 ATen operators supported in this initial release.
Did Amazon do something similar?
Yes. AWS introduced TorchNeuron, its own native PyTorch backend for Trainium chips, as an Apache 2.0 public beta on October 20, 2026, the same day as Google’s TorchTPU open-source release.
Is TorchTPU already used in production?
Google says TorchTPU is already used in production for some inference and training workloads by large Google Cloud customers, even as the open-source project itself remains under active development.
Related Coverage
Yusuf Demir
Yusuf Demir is the Cloud & Software Reporter at TrendinTech, where he covers cloud infrastructure, enterprise platforms, developer tools and the digital transformation of businesses in the UK and the United States. He is most interested in the gap between vendor roadmaps and the systems engineers actually run, and in what the cloud bill looks like once the free credits expire.
All stories by Yusuf Demir (404)